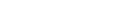
The routes that take a page position answered 400 with a raw framework message naming an internal parameter — destPageNum, pageSet, or newPageNumber — none of which appear in the request, and carried no instanceDetail for a client to map the failure onto a field. An out-of-range pageRange on the same routes already returned a clear message naming the field and its valid range; page positions now match it, and the message is localized like the rest. The status code is unchanged at 400, and the document was never modified by the failing request.
POST /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/Move — destinationPageNumberPOST /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/Copy — destinationPageNumber, validated against the destination entry rather than the sourcePOST /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages — pageNumberPUT /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/{pageNumber}POST /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/{pageNumber}/Image/RotateGET /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/{pageNumber}/ImageGET /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/{pageNumber}/TextGET /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/{pageNumber}/Text/OffsetsGET /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/{pageNumber}/WordLocationsA position that places pages — destinationPageNumber on move and copy, pageNumber on page creation — may be one greater than the document's page count, because after the last page is a legal position. A position that names an existing page may not. Positions inside the valid range are unaffected.
The annotation routes that address a page by number now report an out-of-range pageNumber the same way, naming the field instead of an internal parameter.
POST /Repositories/{repositoryId}/Entries/{entryId}/Pages/{pageNumber}/AnnotationsPATCH and DELETE on /Repositories/{repositoryId}/Entries/{entryId}/Pages/{pageNumber}/Annotations/{itemId}PUT /Repositories/{repositoryId}/Entries/{entryId}/Pages/{pageNumber}/Annotations/{itemId}/AttachmentPUT /Repositories/{repositoryId}/Entries/{entryId}/Pages/{pageNumber}/Annotations/{itemId}/ImageOn the annotation read routes — listing a page's annotations, and reading a single annotation or its attachment — a page past the end of the document continues to answer 404 exactly as before. Only a page number below 1 is reported as a 400.
part=Text on a document with no pages was passed to the export service, which failed the export with Error: Document has no text., surfacing as a 500. Text is stored on pages, so such a document has no text to export and a retry could never succeed. The request is now rejected before any export job starts, with 400 and Error: This entry has no pages., the same error part=Image already gives for that document. How the 400 reaches the caller depends on the route:
POST /Repositories/{repositoryId}/Entries/{entryId}/Export responds 400 instead of 500.POST /Repositories/{repositoryId}/Entries/{entryId}/ExportAsync still responds 202 with a task ID, as it does for every accepted request. The task then fails with a 400 error instead of a 500 one, so read the failure from the task status, not from the response to the start request.A document whose pages have not been generated yet, such as a recently uploaded electronic document, is rejected the same way; retry once pageCount on the entry is greater than zero.
Responses with status 429 Too Many Requests and 503 Service Unavailable now include a Retry-After header with the number of seconds to wait before retrying. The header is exposed to browser callers through CORS.
Every 429 response body now has a limitType member when the limit is known: rateLimit, ioRateLimit, concurrentSearches, concurrentOperations or repositorySessions. Concurrency limits also carry limitScope: principal (the service principal, or the access token for a user) or account. Use them to tell a rate limit (wait and retry) from a concurrency limit (finish or cancel running searches or tasks first). 413 responses carry limitType: requestSize. type, errorCode and title are unchanged, and new limitType values may be added later. A 503 can also carry limitType (serverBusy, below).
detailProblem details now set detail to the error message on every error response. The message is also still in title.
instance and operationId correctly400 and 413 responses for malformed or oversized request bodies returned the operation id in instance and the request path in operationId. They are now the right way round.
503 Service Unavailable when the repository server cannot be reachedWhen the API server could not connect to the repository server, requests answered 500 Internal Server Error. They now answer 503 Service Unavailable with the error class serviceUnavailable and a Retry-After header, so clients can tell a temporary outage from a failed operation and retry later. A failure after the request reached the repository server still answers 500.
503 Service Unavailable when the session store is unavailableWhen the API server's session store was briefly unreachable, too slow or still starting up, requests answered 500 Internal Server Error, or 401 with "no existing session". They now answer 503 Service Unavailable with the error class serviceUnavailable and a Retry-After header. A 401 still means the session or token is not valid.
limitType: serverBusyWhen a server is already working on as many requests as it can, it can now answer a new request with 503 Service Unavailable, limitType: serverBusy and a Retry-After header after waiting at most about a second, instead of holding it until it times out. The request has not been started, so it is safe to send again after the delay in Retry-After. type and errorCode are those of every other 503 (serviceUnavailable, 227); limitType tells this case apart from a 503 for a dependency that cannot be reached.
A service principal can now have up to 10 open searches per access token. It was limited to 6. The account-wide limit of 15 is unchanged.
A multipart upload larger than the import size limit could reach the client as 503. It is now rejected with 413 and errorCode 221 before the body is read.
Repository server errors 9017 (a field value is invalid for its type), 9028 (required data is missing) and 9368 (a rules-based dynamic field could not be evaluated with the given inputs) answered 500. They now answer 400, and the repository error code stays in errorCode. They are most often seen on POST /Repositories/{repositoryId}/Entries/{entryId}/Fields/GetDynamicFieldLogicValue, but the mapping applies to every route.
POST /Repositories/{repositoryId}/Entries/{entryId}/Export and POST /Repositories/{repositoryId}/Entries/{entryId}/Folder/Import waited a fixed second between status checks, so even a small document took more than a second. The server now checks with a short back-off. For 150 to 200 KB PDFs, export p50 went from about 1.15 s to about 0.5 s. Responses are unchanged.
A folder listing that a client stopped paging through was kept open on the repository server for as long as the client kept making other requests. Many of these could exhaust the server's per-session capacity and cause unrelated requests to fail under load. A listing that has not been used for five minutes is now closed. Paging with a $skiptoken is unaffected; a listing closed after five idle minutes is reopened on the next page request.
After a document was moved, GET /Repositories/{repositoryId}/Entries/{entryId}/Folder/Children could return the folder's listing from before the move for up to five minutes. The next request now returns the current listing.
New GET /Repositories/{repositoryId}/Entries/{entryId}/Document/Edoc returns the electronic document as the response body, with no export task, polling or download link.
Content-Type is the stored MIME type, Content-Disposition is attachment with the entry name, and Accept-Ranges: bytes is set.Range header with a single byte range (bytes=a-b, bytes=a-, bytes=-n) returns 206 with Content-Range. A range that starts at or past the end returns 416 with Content-Range: bytes */size. Multiple ranges, another unit, or an unparsable value return 400.400 before anything is read; download a larger document in Range chunks, or use Export.auditReasonId and auditReasonComment are required when the repository requires an export audit reason (400 otherwise). When a reason is given, one export audit event is recorded per download, for the request whose range starts at byte 0.404 for a folder, a missing entry, or a document without an electronic document.429 and Retry-After instead of waiting. When the server is temporarily short of memory for the requested range, it returns 503 with Retry-After; retry after that delay.imageOptions.encodingExportAsync and Export write TIFF image exports uncompressed, so an export can be many times the size of the stored document. A new optional imageOptions.encoding chooses the page compression:
AsStored copies the stored pages without decoding them, so the export is about the size of the stored document. Black-and-white pages stay CCITT G4, colour pages stay LZW, and JPEG pages are written as JPEG inside the TIFF (compression 7), which some older TIFF readers cannot open. Pages that must be redrawn (annotations, redactions, rotation, a watermark) are written G4 or LZW.Uncompressed is today's output.G4 converts every page to black and white.LZW writes every page lossless at its own bit depth.JPEG re-encodes pages as JPEG inside the TIFF using jPEGCompressionLevel; unannotated black-and-white pages stay G4.encoding applies to MultiPageTIFF and SinglePageTIFF only; another format with an encoding is rejected with 400 (imageOptions.encoding), and for ExportAsync the export task fails with it. Omitted, nothing changes.
POST /Repositories/{repositoryId}/TemplateDefinitions persists the template before it applies the fields array, so a failure while assigning those initial fields previously left the newly created template in the repository. Callers saw an error for a template that now existed, and retrying the same request then failed with 409 Object already exists for a name they had never successfully used. The create is now all-or-nothing: if any initial field assignment fails, the template is deleted before the error is returned. The original failure is always the one reported — if the rollback itself fails, that is logged and the template may remain.
POST /Repositories/{repositoryId}/TemplateDefinitions/{templateId}/Fields/Move returned 500 with a raw framework message (Index must be within the bounds of the List.) when newPosition was exactly one past the last field, even though the route documents 400 for an out-of-range position. The position is now validated against the template's field count before the move is attempted, so the response is 400 with a message naming the valid range. Positions inside the range are unaffected, and the field order was never modified by the failing request.
POST /Repositories/{repositoryId}/Entries/{entryId}/ExportAsync and the simple export route rejected part=Image only when the document had no pages at all. A document whose pages carry no image data (text or OCR only) was accepted, and the export then failed inside the export service, surfacing as 500 with the message Export failed with reason: The document has no image pages.. Both routes now check the document's image page count up front and return 400 before the export operation starts. Documents that do have image pages are unaffected.
POST /Repositories/{repositoryId}/Entries/{entryId}/Export and .../ExportAsync accepted part=Text on a document whose pages carry an image but no text stream, and the export then failed inside the export service. On the long-operation path that was worse: the operation was accepted, ran to completion, and handed back a download link that then failed, reporting success for an export that produced nothing. Both routes now check the document's text page count up front and return 400 naming the condition. Text is extracted asynchronously after an import, so a document may briefly have pages and no text — poll hasText on ListPageInfos and retry once it reports true. A document with no pages at all is not rejected here, so its repository-sourced error still reaches the caller unmasked.
POST and PATCH on /Repositories/{repositoryId}/Entries/{entryId}/Pages/{pageNumber}/Annotations returned 200 with the server-assigned members unpopulated: pageNumber was 1 whatever page had been annotated, creator was null, and createdTime and lastModifiedTime were 0001-01-01T00:00:00Z. The update response reported the pre-update lastModifiedTime. All four now carry the stored values. The annotation itself was always stored correctly — a subsequent GET returned the right values — so no stored data was affected and nothing needs re-saving.
The link returned by POST .../Export, and the link an export task reports in result.uri, can be downloaded once. The first GET returns the file; any later GET of the same link answers 404, and that 404 comes from the download service rather than from this API, so it carries no problem details. Save the content on the first download, and start a new export if a download has to be retried. This has always been the behavior; it was previously undocumented.
Operations that the repository client refuses because the connected repository server predates the feature (reported as errorCode 7002, with a message naming the minimum supported version) returned 500. The refusal is deterministic — the same request can never succeed against that server — so returning 500 invited retries that could not help. These now return 400, keeping errorCode 7002 so the condition remains identifiable. One known case is the per-template localDescription property on a template field assignment, which is still refused; only the status code and its retry semantics change here.
The description of POST /Repositories/{repositoryId}/Entries/{entryId}/Document/GenerateText stated that it performed OCR on a document's image pages. It never has: it queues text extraction from the document's electronic document part, so on a document whose pages are images there is nothing to extract and the call produces no text. The wording reached the generated client libraries as well as the API reference. It now describes what the call actually does, and states that a 200 means the request was queued rather than that text exists. Behavior and status codes are unchanged. The generateText and generateImagePagesText flags on the page-write and import routes carried the same claim and are corrected to match.
[BREAKING] PUT .../Tags and PUT .../Links are overwrite actions. A request whose body does not carry the collection member at all — an empty body, {}, or a body that names the member incorrectly — is now rejected with a 400 that names the expected member, instead of being applied as an empty collection. Previously such a request succeeded and unassigned every tag (or removed every link) on the entry. Sending the member with an explicit empty list is unchanged: that still clears the collection, and remains the documented way to unassign everything. Callers that today send no body, or a null member, in order to clear a collection will now receive a 400; they must send the member with an explicit empty list instead.
PUT /Repositories/{repositoryId}/Entries/{entryId}/Tags — tags is required.PUT /Repositories/{repositoryId}/Entries/{entryId}/Links — links is required.The same requirement applies to the remaining overwrite routes. On the access-control routes this is more than data loss: dropping an explicit Deny ace lets the trustee fall back to an inherited Allow, so a malformed body could widen access rather than only clear it.
PUT /Repositories/{repositoryId}/Entries/{entryId}/Fields — fields is required.PUT /Repositories/{repositoryId}/Entries/{entryId}/AccessControl — entries is required.PUT /Repositories/{repositoryId}/FieldDefinitions/{fieldDefinitionId}/AccessControl — entries is required.PUT /Repositories/{repositoryId}/FieldDefinitions/AccessControl — entries is required.PUT /Repositories/{repositoryId}/TemplateDefinitions/{templateId}/AccessControl — entries is required.PUT /Repositories/{repositoryId}/TemplateDefinitions/AccessControl — entries is required.A document can carry named binary streams alongside its primary electronic document -- an audio recording, a source scan, sidecar data -- which travel with it through copy, move, versioning, and briefcase operations. These are now readable over REST. Stream names are at most 15 characters and are limited to ASCII letters, digits, and a small set of punctuation; they are matched exactly, with no case folding, because a name differing only in letter case identifies a different stream on some repository configurations. Streams reserved for internal use are omitted from the listing and reported as not found. The name is passed as a query parameter rather than a path segment because the legal character set includes characters that are significant to OData URI parsing.
GET /Repositories/{repositoryId}/Entries/{entryId}/Document/AlternateEdocs -- paged listing of the document's alternate electronic documents, each with its name, MIME type, and size.GET /Repositories/{repositoryId}/Entries/{entryId}/Document/AlternateEdoc?name={name} -- metadata for a single alternate electronic document.A document also reports hasAlternateEdocs, so a client can tell whether to enumerate at all without a second call. It is populated on a single-entry GET and is null in listing results, where the value is not determined -- null means "not determined here" rather than "none", and it is not selectable on listings.
Alternate electronic documents can now be created, replaced, and deleted over REST. A write is create-or-replace: the stream is created when the document has none under that name, and its content fully replaced when it does. Repeating an identical request is safe. The primary electronic document, the pages, and the metadata are never touched. Content is sent as multipart/form-data under the form field file, with an optional mimeType form field (at most 127 characters) that overrides the type derived from the upload; a zero-byte file is rejected, since removing a stream is what delete is for.
Names follow the same rules the read endpoints publish: at most 15 characters, limited to ASCII letters, digits, and a small set of punctuation, matched exactly. A write whose name differs from an existing stream's only in letter case is refused with 409 rather than performed, because letter case is significant on some repository configurations and not on others -- the same request would otherwise create a second stream on one and silently overwrite a different stream's content on another. Reads and deletes stay exact-match, so a stream is always addressed by the name it was stored under. Names reserved for internal use are rejected.
PUT /Repositories/{repositoryId}/Entries/{entryId}/Document/AlternateEdoc?name={name} -- creates or replaces the content, returning the stored name, MIME type, and size.DELETE /Repositories/{repositoryId}/Entries/{entryId}/Document/AlternateEdoc?name={name} -- deletes the alternate electronic document.Alternate electronic documents can now be written from a file uploaded in chunks, for content too large to send in a single request -- a long audio or video recording, a high-resolution source scan. Upload the content with the existing CreateMultipartUploadUrls flow, then pass the same uploadId and part ETags here; no new upload mechanism is involved, and there is no size limit at this tier beyond the one the upload itself enforces. The operation runs in the background: it returns 202 Accepted with a task ID, and progress and the result are polled from /Tasks?taskIds={taskId}. Use the PUT operation instead for content small enough to send at once, which completes synchronously.
Create-or-replace, the name rules, the exact-match behavior, the reserved names, and the 409 on a name differing only in letter case are all identical to the synchronous write. The name, the MIME type, and the case rule are checked before the operation is accepted, so those errors come back on the request itself rather than on the task. The optional mimeType (at most 127 characters) sets the type recorded for the content; when omitted, the MIME type supplied to CreateMultipartUploadUrls is recorded instead.
POST /Repositories/{repositoryId}/Entries/{entryId}/Document/AlternateEdoc/WriteUploadedParts?name={name} -- starts the write and returns a task ID.The content of an alternate electronic document can now be read back, through the same audited export surface used for the primary electronic document. part accepts a new value, AlternateEdoc, with the stream named in alternateEdocName; the response is the same download link the other parts return. pageRange is ignored, as it is for Edoc.
The name is resolved before the export starts, so a name the document does not carry answers 404 on the request rather than failing inside the export. A name reserved for internal use is reported as not found. A name supplied with any other part is rejected with 400 rather than ignored, so a caller who asks for a named stream never silently receives the primary electronic document instead.
POST /Repositories/{repositoryId}/Entries/{entryId}/Export -- part=AlternateEdoc with alternateEdocName.POST /Repositories/{repositoryId}/Entries/{entryId}/ExportAsync -- the same, as a long operation.POST /Repositories/{repositoryId}/Entries/{entryId}/Document/GenerateText takes a new optional query parameter, ocrImagePages. It defaults to false, which is exactly today's behavior: the call queues text extraction from the document's electronic document part, and does nothing for a document whose pages are images.
Set ocrImagePages=true and the call also queues an OCR job for the document's image pages. Only pages that have an image and no text are included. A page that already has text is left alone, because OCR replaces a page's text and would otherwise discard text that was written through WritePage or edited by a user. To re-OCR a page that already has text, clear that text with WritePage first and then call GenerateText with ocrImagePages=true.
The response is unchanged: 200 with the entry, meaning the request was queued, not that text now exists. OCR runs asynchronously and a large document may stay queued for some time. Poll hasText on ListPageInfos to observe the result.
Two cases are refused up front rather than queued, because OCR writes its results back under an exclusive lock and a held document cannot be processed:
423 when another user holds a lock on the document.400 when another user has the document checked out.At most 511 pages can be queued in one request; a document with more image pages that have no text returns 400. That is the number of pages the OCR pipeline accepts in a single job.
The repository's automatic OCR setting does not apply to ocrImagePages. It governs only the OCR the repository performs on its own when a page image is written; a request made through the API is explicit, and its OCR is queued whether that setting is on or off.
The language the OCR engine uses is the document's own language, then the repository's configured default, then en. Pass ocrLanguageOverride with an RFC 4646 code such as en to name the language for a single request instead. It applies to that request only: the document's stored language is not changed, so the repository's automatic OCR keeps using it. A value that is not a usable language code returns 400 rather than being queued -- and so does one inherited from the document or the repository, because a job queued with an unusable language is accepted and then produces no text, with nothing reported back to the caller. Supplying ocrLanguageOverride without ocrImagePages=true returns 400.
Automatic OCR when a page image is first written is unchanged, and a document that has no image pages without text is a success that queues nothing.
A page's recognized text can now be related to positions on the page image. ListPageWordLocations returns every word of a page in reading order with its text offsets and its rectangle; GetPageTextOffsets takes a rectangle and returns the span of page text it covers. Together they let a caller map a selection on a page image to a range in the page text, and back — the basis for redaction and highlight tooling.
Two conventions matter. Coordinates are raw unrotated image pixels, the space the page image is stored in, not display pixels — a page shown rotated needs the rotation applied by the caller. Offsets are UTF-16 code-unit indexes into the page text with an exclusive textEnd, the same convention text-linked annotations use, so a span read here can be written straight back to an annotation.
A page whose word locations have not been generated answers 404; word locations come from text recognition, so a page that has never been recognized has none. A rectangle covering no word returns hasTextSpan: false rather than an error. The number of words read from one page is bounded by service configuration; a page exceeding the bound is refused rather than truncated, because a truncated word list would silently mis-pair with the page text.
GET /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/{pageNumber}/WordLocationsGET /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/{pageNumber}/Text/Offsets?x=&y=&width=&height=Cross-origin browser requests continue to work from any origin, but responses no longer include Access-Control-Allow-Credentials. Requests authenticated with a bearer Authorization header — the supported authentication for this API — are unaffected: that header does not require the credentials grant. Only requests relying on browser-managed credentials (for example fetch with credentials: 'include') are affected; those were never a supported authentication path. Deployments can additionally restrict cross-origin access to an explicit list of origins through service configuration.
Document import can now target a folder path relative to the route entry, creating any missing folders along the way ("mkdir -p"). A new optional folderPath body property carries a path relative to {entryId} (both / and \ are accepted as separators); the Name is still the document name. A new autoCreateFolderPath query parameter (default false) gates creation: when false, any missing folder in the path returns 404; when true, missing folders are created. Existing folders in the path are reused; a path segment whose name is already taken by a non-folder returns an error, and autoRename never applies to the path segments (only to the document). Omitting folderPath is unchanged behavior. Folder names are limited to 255 characters and the full resulting path to 1023 characters. Folder creation is not transactional: if the request still fails after the path is created (for example, a name conflict on the document), any folders created along the way remain.
POST /Repositories/{repositoryId}/Entries/{entryId}/Folder/Import — folderPath + autoCreateFolderPath.POST /Repositories/{repositoryId}/Entries/{entryId}/Folder/ImportUploadedParts — folderPath + autoCreateFolderPath.POST /Repositories/{repositoryId}/Entries/{entryId}/Folder/Children (create folder or shortcut) accepts the same optional folderPath body property and autoCreateFolderPath query parameter, creating the entry under the resolved (and, when the flag is set, auto-created) folder path. Semantics match import: existing folders reused, non-folder name collisions rejected, autoRename applies only to the created entry (not the path segments), and omitting folderPath is unchanged behavior. As with import, folder creation is not transactional — folders created along the way remain even if creating the final entry fails.
Document annotations can now be read over REST. Annotations are returned as a polymorphic list discriminated by annotationType (a common header — itemId, pageNumber, creator, createdTime, lastModifiedTime, comment, visibility, isProtected, zOrder, reasonId, accessType — plus type-specific properties for each of the 14 annotation types: highlight, redaction, strikeout, underline, note, attachment, text box, bitmap, line, rectangle, polyline, callout, stamp, and freehand). Geometry is in image pixels ({x, y, width, height}); colors are #RRGGBB strings (null when transparent). Reading requires the "see annotations" entry right; redaction content is governed by the "see through redactions" right.
GET /Repositories/{repositoryId}/Entries/{entryId}/Annotations — list all annotations on a document.GET /Repositories/{repositoryId}/Entries/{entryId}/Pages/{pageNumber}/Annotations — list annotations on a page.GET /Repositories/{repositoryId}/Entries/{entryId}/Pages/{pageNumber}/Annotations/{itemId} — get a single annotation.GET /Repositories/{repositoryId}/Entries/{entryId}/Pages/{pageNumber}/Annotations/{itemId}/Attachment — stream the content of an attachment annotation.GET /Repositories/{repositoryId}/AnnotationReasons — list the repository's redaction reasons.Document annotations can now be created, updated, and deleted over REST. The create body is the same polymorphic shape as the read response (discriminated by annotationType); update is a partial patch (omitted members are unchanged, and annotationType must match the existing annotation). Writing requires the "annotate" entry right. All operations are atomic — server-side page locking is handled within the single request.
POST /Repositories/{repositoryId}/Entries/{entryId}/Pages/{pageNumber}/Annotations — create an annotation of any of the 14 types. Returns the created annotation (with its assigned itemId).PATCH /Repositories/{repositoryId}/Entries/{entryId}/Pages/{pageNumber}/Annotations/{itemId} — partial update of an annotation's writable members.DELETE /Repositories/{repositoryId}/Entries/{entryId}/Pages/{pageNumber}/Annotations/{itemId} — delete an annotation.PUT /Repositories/{repositoryId}/Entries/{entryId}/Pages/{pageNumber}/Annotations/{itemId}/Attachment — upload (multipart/form-data) the content of an attachment annotation. Create the attachment annotation first, then upload its bytes here.PUT /Repositories/{repositoryId}/Entries/{entryId}/Pages/{pageNumber}/Annotations/{itemId}/Image — upload (multipart/form-data) the image of a bitmap annotation.POST /Repositories/{repositoryId}/AnnotationReasons — create a redaction reason.PATCH /Repositories/{repositoryId}/AnnotationReasons/{reasonId} — update a reason's text.DELETE /Repositories/{repositoryId}/AnnotationReasons/{reasonId} — delete a reason. Pass force=true to delete a reason that is in use.The repository stamp catalog (public and personal stamps) is now manageable over REST. Catalog metadata is returned without the image bytes; the stamp image is fetched and uploaded separately as a PNG. Managing a public stamp requires the stamp-management privilege; personal stamps require no special privilege.
GET /Repositories/{repositoryId}/Stamps?scope=public|personal|all — list stamps.GET /Repositories/{repositoryId}/Stamps/{stampId} — get a stamp's metadata.GET /Repositories/{repositoryId}/Stamps/{stampId}/Image — download a public stamp's image as a PNG (optional color=#RRGGBB). Only public/common stamps are served; personal stamps return 404.POST /Repositories/{repositoryId}/Stamps — create a stamp from an uploaded image (multipart file; name and isPublic are query parameters). The service converts the image to the repository's internal format.PATCH /Repositories/{repositoryId}/Stamps/{stampId} — update a stamp's name and/or custom data. The image is immutable after creation.DELETE /Repositories/{repositoryId}/Stamps/{stampId} — delete a stamp.The per-user Recent Documents and Recent Folders lists maintained by the Laserfiche apps are now readable over REST. Both endpoints are read-only and return entries most-recently-accessed first; if the user has no recents, an empty collection is returned.
GET /Repositories/{repositoryId}/RecentDocuments — returns the authenticated user's recently accessed documents (entryId, fullPath). Optional documentLimit query parameter caps the number of results (0 returns an empty list; negative values are rejected).GET /Repositories/{repositoryId}/RecentFolders — returns the authenticated user's recently accessed folders (entryId, fullPath).The per-user Starred list is now readable and writable over REST.
GET /Repositories/{repositoryId}/StarredEntries — returns the authenticated user's starred entries (entryId, fullPath).POST /Repositories/{repositoryId}/StarredEntries — stars one or more entries (entryIds); idempotent for already-starred entries. Creates the user's Starred area on first use. Returns the updated list.DELETE /Repositories/{repositoryId}/StarredEntries — unstars one or more entries (entryIds); idempotent. Returns the updated list.Per-user Personal Collections (named sets of entries) now have full CRUD over REST. Each collection has a stable id, a display name, and member entryIds. Names must be unique (case-insensitive), 256 characters or fewer, and must not use a reserved name (Starred, Recent Documents); a user may have at most 50 collections.
GET /Repositories/{repositoryId}/PersonalCollections — list the user's collections.POST /Repositories/{repositoryId}/PersonalCollections — create a collection (name). 409 on duplicate/reserved name; 400 on too-long name or when the 50-collection limit is reached.GET /Repositories/{repositoryId}/PersonalCollections/{collectionId} — get a single collection.PATCH /Repositories/{repositoryId}/PersonalCollections/{collectionId} — rename a collection (name).DELETE /Repositories/{repositoryId}/PersonalCollections/{collectionId} — delete a collection (idempotent; 204).POST / DELETE /Repositories/{repositoryId}/PersonalCollections/{collectionId}/Entries — add or remove member entries (entryIds); returns the updated collection.The raw user-area primitive is now exposed for the caller's own areas. Application-managed areas (Personal Collections, Starred, Recent) are hidden from this surface so a raw write cannot corrupt the app conventions. (Owner-targeting via ?sid= for service-principal/admin scenarios is a planned follow-up.)
GET /Repositories/{repositoryId}/UserAreas — list the caller's user areas (id, name, comment, data).POST /Repositories/{repositoryId}/UserAreas — create a user area (name, optional comment/data). Reserved names are rejected.GET /Repositories/{repositoryId}/UserAreas/{areaId} — get a user area.PUT /Repositories/{repositoryId}/UserAreas/{areaId} — partial update (name/comment/data; null leaves unchanged).DELETE /Repositories/{repositoryId}/UserAreas/{areaId} — delete a user area (204).GET / POST / DELETE /Repositories/{repositoryId}/UserAreas/{areaId}/Entries — list, add, or remove member entries (entryIds).Applications can now read and manage access rights across the repository's securable scopes — entries, fields, and templates — plus the current session's rights, trustee lookup, and trustee account security. All of these operations share a single AccessControl API group (one AccessControlClient in the client libraries); their routes stay nested under the resource they secure.
A single rights query per securable object replaces the originally separate effective/direct routes: each Rights endpoint takes an aclOnly flag — aclOnly=false (default) returns the net effective rights (after inheritance, group membership, allow/deny resolution, and the privilege / records-management overlays); aclOnly=true returns only the rights granted by the object's own ACL, without the privilege/RM overlay (group membership still resolved). Both modes also return isReadOnly. The trustee query is by ?trusteeId={sid} or ?trusteeName={name}; omitting it resolves to the calling session.
GET /Repositories/{repositoryId}/Entries/{entryId}/AccessControl[?includeInherited=] — returns the entry's access control list: the access control entries (each with trustee, accessControlType (Allow/Deny), the granted/denied rights, and propagation scope) plus whether the entry inherits rights from its parent(s). includeInherited=true (default) returns both explicit and inherited ACEs (inherited carry isInherited = true); includeInherited=false returns only the explicit ACEs — the exact set the PUT accepts.PUT /Repositories/{repositoryId}/Entries/{entryId}/AccessControl — full replace of the entry's explicit access control entries (an empty array clears it; inherited entries cannot be supplied; inheritParents controls inheritance — omit to preserve). Each entry is keyed by trustee.sid. Returns the updated ACL.GET /Repositories/{repositoryId}/Entries/{entryId}/Rights[?trusteeId=|?trusteeName=][&aclOnly=] — the entry rights query described above.GET / PUT /Repositories/{repositoryId}/FieldDefinitions/{fieldId}/AccessControl — read / full-replace a field definition's ACL.GET /Repositories/{repositoryId}/FieldDefinitions/{fieldId}/Rights[?trusteeId=|?trusteeName=][&aclOnly=] — the field rights query.GET / PUT /Repositories/{repositoryId}/FieldDefinitions/DefaultAccessControl — read / replace the default ACL applied to newly created fields.GET / PUT /Repositories/{repositoryId}/TemplateDefinitions/{templateId}/AccessControl, GET /Repositories/{repositoryId}/TemplateDefinitions/{templateId}/Rights[...], and GET / PUT /Repositories/{repositoryId}/TemplateDefinitions/DefaultAccessControl — the template-definition equivalents.GET /Repositories/{repositoryId}/SessionRights — the current session's privileges and feature rights (named-boolean maps) plus isReadOnly, for UI enablement and pre-flight checks. Reflects the current session only.GET /Repositories/{repositoryId}/Trustees?search={name}&type={user|group}&count={n} — searches users and groups by name, returning each match's SID, account name, display name, type, whether it is a user or group, and whether it is disabled. Use it to resolve names to the SIDs used when building access control entries or addressing a trustee.GET /Repositories/{repositoryId}/Trustees/{trusteeId}/Security[?includeInherited=] — a trustee's repository-level privileges, feature rights, security tags, and success/failure audit masks (named-boolean maps) plus isReadOnly. includeInherited=true (default) returns the effective security — what applies once the trustee's group memberships are resolved (a documented best-effort computation; the authoritative reading is to sign in as that trustee). includeInherited=false returns the direct security assigned on the trustee record itself, without group-membership inheritance.The ACL read/write operations carry a two-layer permission model: the repository.Read/repository.Write OAuth scope is necessary but not sufficient — the repository session additionally enforces the object-level right (e.g. ReadPermissions to read an entry ACL, ChangePermissions to replace one) and returns 403 when it is lacking.
Applications can now read and manage the records management state of entries over REST. Computed (read-only) members are marked as such in the schema.
GET /Repositories/{repositoryId}/Entries/{entryId}/RecordsManagement/Properties — returns the records management properties of a record or record folder as a single shape discriminated by recordType (record | recordFolder); members that do not apply to the entry's type are omitted. Returns 404 when the entry is not a record or record folder.PATCH /Repositories/{repositoryId}/Entries/{entryId}/RecordsManagement/Properties — updates the writable subset (null leaves a member unchanged; id members accept 0 to clear; the record-folder triggerDate and record lastReviewDate are cleared via their clear* flags). Applying this to a plain document promotes it to a record, and to a plain folder promotes it to a record folder, before the properties are applied; members not applicable to the resulting type are rejected with 400.POST /Repositories/{repositoryId}/Entries/{entryId}/RecordsManagement/SetEvent and .../RemoveEvent — set or remove a records management event date on a record or record folder.GET /Repositories/{repositoryId}/Entries/{entryId}/RecordsManagement/EligibleRecords?eligibleFor=disposition|transfer — returns the ids of the records under a record folder that are eligible for the requested action.GET /Repositories/{repositoryId}/Entries/{entryId}/RecordsManagement/IndependentRecords — returns the ids of the independent records under a record folder.GET /Repositories/{repositoryId}/Entries/{entryId}/RecordsManagement/AltRetentionEvents — returns a record folder's alternate-retention trigger events.GET / PATCH /Repositories/{repositoryId}/Entries/{entryId}/RecordSeries/Properties — read / update a record series' cascading retention defaults; the update's cascade flag applies the change to the file plan beneath the series.POST /Repositories/{repositoryId}/Entries/{parentEntryId}/RecordSeries — create a record series under a parent folder (name, code). Delete uses the existing Delete Entry endpoint.Read operations require repository.Read; write operations require repository.Write. The repository's Records Management feature and the applicable records management privilege / entry rights are additionally enforced by the server.
POST /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/{pageNumber}/Image/Rotate previously returned 200 OK without actually saving the rotation — the page's imageRotationAngle was left unchanged and the page still rendered in its original orientation. The rotation is now persisted, so a subsequent read (e.g. ListPageInfos) reflects the new imageRotationAngle and viewers display the rotated page.
GET /Repositories/{repositoryId}/Entries/{entryId} gains two opt-in query parameters. Both are comparatively expensive to compute, so they are omitted from the response unless explicitly requested:
includeChildInfo=true (folder entries) — returns a childInfo object { hasChildren, childCount, folderCount, documentCount, shortcutCount } describing the folder's immediate children (total plus per-type counts). Counts are for immediate children only — recursive/whole-subtree counts are intentionally not offered. For folder tree navigation, prefer optimistic lazy expansion (load children on demand) over requesting this per node.includeTotalSize=true (document entries) — returns totalDocumentSize, the document's full stored size (electronic document plus page image/text/locations/thumbnail data and attachments), as opposed to electronicDocumentSize, which is just the source file.Repository administrators can now create and manage metadata field definitions over REST. Previously the FieldDefinitions surface was read-only.
POST /Repositories/{repositoryId}/FieldDefinitions — create a field definition. name and fieldType are required; the request also accepts the writable definition attributes (description, length, format/formatPattern, constraint/constraintError, currency, defaultValue) and behavior flags (isIndexed, isIndexedForReporting, isMultiValue, isRequired, warnIfBlank, hideListValues, autoExtract), plus an optional properties extended key-value bag and initial listValues for List-type fields. Returns the created definition.PATCH /Repositories/{repositoryId}/FieldDefinitions/{fieldId} — partial update of writable properties. Only supplied properties change; null leaves a property unchanged and "" clears a string property. fieldType cannot be changed here (use ChangeType) and list values are managed through the dedicated ListValues resource.DELETE /Repositories/{repositoryId}/FieldDefinitions/{fieldId} — delete a field definition. Returns 409 if the field is still referenced by templates or assigned to entries.GET / PUT /Repositories/{repositoryId}/FieldDefinitions/{fieldId}/ListValues — read or wholesale-replace the pick-list values of a List-backed field. PUT preserves client-supplied order; an empty array clears the list. Non-list fields are rejected with 400.GET /Repositories/{repositoryId}/FieldDefinitions/{fieldId}/ContainingTemplates — list the template definitions that include this field.GET /Repositories/{repositoryId}/FieldDefinitions/{fieldId}/AssignedEntryCount — count of entries currently using this field.GET / PATCH /Repositories/{repositoryId}/FieldDefinitions/{fieldId}/Properties — read or update the field's extended properties bag (a string key-value store for integration metadata and application-specific configuration that persists with the field definition).Administrators can now consolidate or convert existing field definitions:
POST /Repositories/{repositoryId}/FieldDefinitions/Merge — merges two or more existing field definitions into a new field. onConflict (Fail (default), MakeMultivalue, UseFirstField) controls how per-entry value conflicts are resolved; UseFirstField discards conflicting values and requires allowDataLoss = true. Optional removeFromTemplates removes the source fields from any templates that contain them; autoRename requests a non-conflicting name when newFieldName collides (best-effort — honoring is repository-version-dependent). The source field definitions themselves are preserved — only their per-entry values are migrated to the new merged field; delete the sources explicitly afterward if no longer needed.POST /Repositories/{repositoryId}/FieldDefinitions/{fieldId}/ChangeType — converts an existing field definition to a different newFieldType. The conversion may reset type-specific configuration (length, constraint, format), clear list items when leaving the List type, and drop default values or per-entry values that don't fit the new type. allowDataLoss = true is required for any conversion the server treats as lossy; the only conversions exempt are the explicit safe widenings Date → DateTime, ShortInteger → LongInteger, ShortInteger → Number, and LongInteger → Number (and only when no other lossy condition applies).Repository administrators can now create and manage metadata template definitions over REST. Previously the TemplateDefinitions surface was read-only.
POST /Repositories/{repositoryId}/TemplateDefinitions — create a template definition. name is required; optional description, color, isAutoAssignable, and an initial fields array (each entry: fieldName, optional isRequired, optional localDescription). Initial fields are applied to the template after creation; if a field assignment fails mid-list the template is created with the partial set (reported, not rolled back).PATCH /Repositories/{repositoryId}/TemplateDefinitions/{templateId} — partial update of template properties (name, description, color, isAutoAssignable). null leaves a property unchanged; for color, an explicit null clears the color.DELETE /Repositories/{repositoryId}/TemplateDefinitions/{templateId} — delete a template definition. Returns 409 if the template is still assigned to entries.GET /Repositories/{repositoryId}/TemplateDefinitions/{templateId}/AssignedEntryCount — count of entries currently assigned this template.GET / PATCH /Repositories/{repositoryId}/TemplateDefinitions/{templateId}/Properties — read or update the template's extended properties bag.POST /Repositories/{repositoryId}/TemplateDefinitions/{templateId}/Fields — add a field to a template. Optional position (1-based) inserts at that position; otherwise the field is appended. Optional per-template isRequired and localDescription.PATCH /Repositories/{repositoryId}/TemplateDefinitions/{templateId}/Fields/{fieldName} — update a field's per-template properties (isRequired, localDescription). The per-template required flag is distinct from the field definition's repository-level required flag.DELETE /Repositories/{repositoryId}/TemplateDefinitions/{templateId}/Fields/{fieldName} — remove a field from the template. Field values already assigned to entries are unaffected.POST /Repositories/{repositoryId}/TemplateDefinitions/{templateId}/Fields/Move — reorder a field within the template via fieldName + newPosition (1-based).The existing GET template endpoints now additionally surface isAutoAssignable on the template and localDescription on each template field.
A Laserfiche document is a composite of an electronic document (optional), image pages, and text pages. New endpoints expose per-page image and text content independently:
POST /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages — create pages (image, text, both, or empty). Optional pageNumber inserts at position; otherwise appends. Optional generateText triggers OCR.PUT /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages — replace all pages in a single call (one lock, one auto-version).PUT /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/{pageNumber} — overwrite image part, text part, or both of an existing page. At least one of imageFile or request.text required.DELETE /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages — delete a range or all pages.POST /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/Move — reorder pages within the same document via a pageRange + destinationPageNumber.POST /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/Copy — copy pages from one document to another. The pageRange is limited to 500 distinct pages per request.POST /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/{pageNumber}/Image/Rotate — rotate the image of a single page by 90/180/270 degrees.GET /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/{pageNumber}/Image — retrieve per-page image content as binary.GET /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages/{pageNumber}/Text — retrieve per-page text content.GET /Repositories/{repositoryId}/Entries/{entryId}/Document/Pages — list page metadata (image/text presence). Optional pageRange filters a subset.POST /Repositories/{repositoryId}/Entries/{entryId}/Document/GenerateText — trigger OCR across all image pages.POST /Repositories/{repositoryId}/Entries({parentEntryId})/Folder/Import now accepts an optional imageFiles parameter (up to 10 files, 100 MB aggregate) and an optional generateImagePagesText flag (default true) that runs OCR on image pages after import. Omitting file — or supplying a zero-length file — creates an empty document with no electronic document and no pages.PATCH /Repositories/{repositoryId}/Entries/{entryId}/Document — unified additive update for the electronic document, metadata (fields, tags, links, template), and image pages. At least one of file, imageFiles, or metadata must be provided. Metadata is additive; imageFiles are appended; a non-empty file replaces the edoc. Zero-length file is rejected with 400 — use DELETE .../Document/Edoc to remove the edoc explicitly.POST /Repositories/{repositoryId}/Entries/{entryId}/Document/UpdateUploadedParts — chunked async counterpart for large files. Assembles previously uploaded parts (from CreateMultipartUploadUrls) and applies optional metadata.DELETE /Repositories/{repositoryId}/Entries/{entryId}/Document/Edoc — remove the electronic document while preserving pages and metadata.PUT /Repositories/{repositoryId}/Entries({entryId})/Template and DELETE /Repositories/{repositoryId}/Entries({entryId})/Template — assign or remove an entry's template. Applies to all entry types.POST /Repositories/{repositoryId}/Entries/{entryId}/Document/Lock — create a persistent lock on a document with optional comment and extent (Page, Edoc, Metadata, or All; default All). Persistent locks survive session disconnect and server restart.GET /Repositories/{repositoryId}/Entries/{entryId}/Document/Lock — retrieve the current lock state (lock token, owner, comment, extent, creation timestamp, active status).DELETE /Repositories/{repositoryId}/Entries/{entryId}/Document/Lock — unlock the current user's lock, or unlock another user's lock administratively via ?lockToken={token}.POST /Repositories/{repositoryId}/Entries/{entryId}/Document/VersionControl — put a document under version control. Required before checkout.POST /Repositories/{repositoryId}/Entries/{entryId}/Document/CheckOut — check out a document. Optional lock (default true) auto-acquires a persistent lock; optional comment attaches a message.POST /Repositories/{repositoryId}/Entries/{entryId}/Document/CheckIn — check in a document, creating a new version. Optional unlock (default true) releases any persistent lock as part of the check-in.POST /Repositories/{repositoryId}/Entries/{entryId}/Document/UndoCheckOut — undo a check-out without creating a new version.GET /Repositories/{repositoryId}/Entries/{entryId} responses for document entries now include the following document-specific fields alongside the existing pageCount, electronicDocumentSize, isCheckedOut, and isUnderVersionControl:
isLocked — whether the document has a persistent lock.lockedBy — display name of the persistent lock holder (nullable).isLockedByAnotherUser — true if locked by a user other than the caller.currentVersion — version number (0 if not under version control).checkedOutBy — display name of the user who checked out the document (nullable).isCheckedOutByAnotherUser — true if checked out by a user other than the caller.The following API is updated to always return entryType, even if the OData $select query options is used and it doesn't include entryType:
GET /Repositories/{repositoryId}/Entries/{entryId}The following API is updated to always return entryType, even if the OData $select query options is used and it doesn't include entryType:
GET /Repositories/{repositoryId}/Searches/{taskId}/ResultsThe following API is updated to always return entryType, even if the OData $select query options is used and it doesn't include entryType:
POST /Repositories/{repositoryId}/SimpleSearchesThe following compares the Laserfiche Repository API V1 with V2 at time of release.
[BREAKING] Restructured the response body to return a single wrapped list for the following API:
GET /Repositories/{repoId}/AuditReasons[NEW] Added export APIs:
POST /Repositories/{repositoryId}/Entries/{entryId}/Export
/ExportAsync if you run into this restriction.POST /Repositories/{repositoryId}/Entries/{entryId}/ExportAsync
/Export API. See below to learn more about the long operations.[BREAKING] Removed export related APIs:
HEAD /Repositories/{repoId}/Entries/{entryId}/Laserfiche.Repository.Document/edocGET /Repositories/{repoId}/Entries/{entryId}/Laserfiche.Repository.Document/edocPOST /Repositories/{repoId}/Entries/{entryId}/Laserfiche.Repository.Document/GetEdocWithAuditReason[NEW] Added import APIs:
POST /Repositories/{repositoryId}/Entries/{entryId}/Folder/Import
/ImportAsync if you run into this restriction.POST /Repositories/{repositoryId}/Entries/CreateMultipartUploadUrls
/ImportUploadedParts API.POST /Repositories/{repositoryId}/Entries/{entryId}/Folder/ImportUploadedParts
/Import API. See below to learn more about the long operations.[BREAKING] Removed import API:
POST /Repositories/{repoId}/Entries/{parentEntryId}/{fileName} [BREAKING] Renamed the request body properties, renamed the response body properties, and changed the success status code to 202 Accepted for the following API:
DELETE /Repositories/{repoId}/Entries/{entryId} [BREAKING] Moved the autoRename query parameter to the request body for the following API:
PATCH /Repositories/{repoId}/Entries/{entryId} [BREAKING] Removed the Laserfiche.Repository. in the URL and changed the response to return an Entry for the following APIs:
DELETE /Repositories/{repoId}/Entries/{entryId}/Laserfiche.Repository.Document/edocDELETE /Repositories/{repoId}/Entries/{entryId}/Laserfiche.Repository.Document/pages [BREAKING] Removed the Laserfiche.Repository. in the URL, renamed the formatFields query parameter, and restructured the fields portion of the response body for the following API:
GET /Repositories/{repoId}/Entries/{entryId}/Laserfiche.Repository.Folder/children [BREAKING] Removed the Laserfiche.Repository. in the URL and moved the autoRename query parameter to the request body for the following API. Additionally, moved the copy functionality out to a new POST /Repositories/{repositoryId}/Entries/{entryId}/Folder/Copy API.
POST /Repositories/{repoId}/Entries/{entryId}/Laserfiche.Repository.Folder/children [BREAKING] Removed the Laserfiche.Repository. in the URL, moved the autoRename query parameter to the request body, renamed the response body properties, and changed the success status code to 202 Accepted for the following API:
POST /Repositories/{repoId}/Entries/{entryId}/Laserfiche.Repository.Folder/CopyAsync [BREAKING] Renamed the formatValue query parameter and restructured the response body for the following API:
GET /Repositories/{repoId}/Entries/{entryId}/fields[BREAKING] Restructured the request body and restructured the response body for the following API:
PUT /Repositories/{repoId}/Entries/{entryId}/fields[BREAKING] Restructured the request body and renamed the response body properties for the following API:
PUT /Repositories/{repoId}/Entries/{entryId}/links[BREAKING] Renamed the response body properties for the following APIs:
GET /Repositories/{repoId}/Entries/{entryId}/linksGET /Repositories/{repoId}/Entries/{entryId}/tagsPUT /Repositories/{repoId}/Entries/{entryId}/tags[BREAKING] Restructured the request body for the following API:
PUT /Repositories/{repoId}/Entries/{entryId}/template[BREAKING] Renamed the response body properties for the following APIs:
GET /Repositories/{repoId}/LinkDefinitionsGET /Repositories/{repoId}/LinkDefinitions/{linkTypeId}[BREAKING] Restructured the response body to return a wrapped list with renamed properties for the following API:
GET /Repositories[BREAKING] Removed APIs for getting a search status and cancelling a search. Use the new v2 Tasks APIs for getting the status and cancelling a set of one or more Tasks, including Search.
GET /Repositories/{repoId}/Searches/{searchToken}DELETE /Repositories/{repoId}/Searches/{searchToken} [BREAKING] Changed the URL to POST /Repositories/{repositoryId}/Searches/SearchAsync, renamed the response body properties, and changed the success status code to 202 Accepted for the following API:
POST /Repositories/{repoId}/Searches [BREAKING] Renamed the formatFields query parameter and restructured the fields portion of the response body for the following API:
GET /Repositories/{repoId}/Searches/{taskId}/Results [BREAKING] In the past, it was necessary to call POST /Repositories/{repoId}/ServerSession/Create first before making any other API calls. This is no longer required as any API can be called after receiving an access token. As a result, the following APIs have been removed.
POST /Repositories/{repoId}/ServerSession/CreatePOST /Repositories/{repoId}/ServerSession/RefreshPOST /Repositories/{repoId}/ServerSession/Invalidate [BREAKING] Renamed the formatFields query parameter and restructured the fields portion of the response body for the following API. Additionally, 200 OK status code is returned with an empty array instead of 204 No Content when no search results are found.
GET /Repositories/{repoId}/SimpleSearches[BREAKING] Renamed the response body properties for the following APIs:
GET /Repositories/{repoId}/TagDefinitionsPUT /Repositories/{repoId}/TagDefinitions/{tagId}[NEW] Added APIs for getting the status and cancelling a set of one or more Tasks.
GET /Repositories/{repositoryId}/TasksDELETE /Repositories/{repositoryId}/Tasks[BREAKING] Removed APIs for getting the status and cancelling a single Task.
GET /Repositories/{repoId}/Tasks/{operationToken}DELETE /Repositories/{repoId}/Tasks/{operationToken}[BREAKING] Getting the status of a Task, now uses the long polling technique and could return the result immediately (e.g. if the long operation failed or completed successfully) or after at most 60 seconds.
[BREAKING] Changed the /Fields portion of the URL to /FieldDefinitions for the following APIs:
GET /Repositories/{repoId}/TemplateDefinitions/{templateId}/FieldsGET /Repositories/{repoId}/TemplateDefinitions/Fields[BREAKING] Applies to the following APIs:
DELETE /Repositories/{repositoryId}/Entries/{entryId}POST /Repositories/{repositoryId}/Entries/{entryId}/Folder/CopyAsyncPOST /Repositories/{repositoryId}/Entries/{entryId}/ExportAsyncPOST /Repositories/{repositoryId}/Entries/{entryId}/Folder/ImportUploadedPartsPOST /Repositories/{repositoryId}/Searches/SearchAsyncLong operations will return a taskId property instead of a token. The taskId will still be used by the Tasks APIs for getting the status and cancelling long operations.
Error handling has now been centralized. Long operations will return a taskId property immediately if possible, and errors (e.g. validation errors or the errors that may occur during the execution of the operation) can be found by checking the status of the long operation using GET /Repositories/{repositoryId}/Tasks. Previously in v1, errors could be returned when creating the API or when checking the status of the long operation.
OAuth 2.0 scopes are mandatory in v2 and will issue a 403 Forbidden response if your access token does not have the correct scopes. See the documentation in the Swagger Playground for the required OAuth scope needed to access each API. Learn more about OAuth scopes here.
Properties with null value are omitted during response serialization, if the corresponding property is a Collection type, or a Nullable Integral type.